Cloud & Kubernetes
Build the foundation. Keep it dependable.
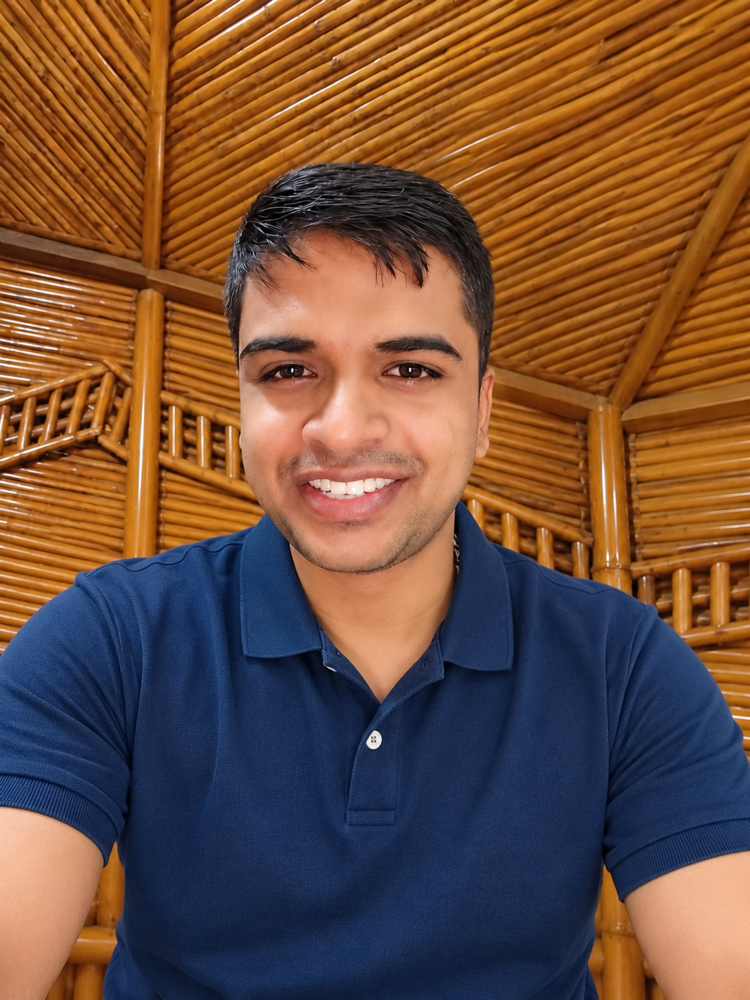
Hi, I’m Vardhan.
Srivardhan Reddy Kolan
Senior DevOps Engineer
I build and operate the infrastructure behind software. AWS, Kubernetes, and automation—with production reliability at the center.
I’m Srivardhan Reddy Kolan, a Senior DevOps Engineer based in Hyderabad. My path started in Linux and application support, then grew into cloud infrastructure, Kubernetes, and platform engineering.
I like the work between a system working once and a system working reliably: repeatable infrastructure, thoughtful release controls, useful monitoring, and a clear understanding of what went wrong.
More about my journeyBuild the foundation. Keep it dependable.
Repeatable infrastructure, reviewed as code.
Make the path to production safer.
Understand the system. Find the cause.
From Linux fundamentals to production platforms.
A career spent close to the systems.
Technical Analyst - DevOps
Supporting the infrastructure behind Bluebeam products, from AWS and EKS operations to production deployment governance.
Senior DevOps Engineer
Worked on AWS migration, Kubernetes operations, and delivery automation, with a focus on reliable production platforms.
DevOps Engineer
Helped move applications from on-premises environments to AWS and made delivery and operations more repeatable.
Sr. Process Associate
Administered Red Hat Linux servers and supported critical environments around the clock.
Linux L2 Production Support Engineer
Built a foundation in Linux operations and L2 application support within an ITIL environment.
A closer look at problems I’ve worked on.
Based on my professional experience.
Example command: terraform plan. Example output: Configuration validated. Plan ready for review. Production approval required. This is an illustration, not a live system.
GitLab approval controls that protect infrastructure changes before a downstream pipeline starts.
Production infrastructure changes need an explicit approval boundary, including when a parent pipeline triggers downstream Terraform jobs.
Designed and validated Protected Environment controls and parent trigger-job behavior using environment action:start before downstream execution.
Approval behavior needs to be validated across pipeline boundaries, alongside the infrastructure plan itself.
Example command: kubectl get pods. Example output: api-server 1/1 Running. worker 1/1 Running. Workloads ready for inspection. This is an illustration, not a live system.
Incident analysis across applications, Kubernetes, and the underlying EC2 infrastructure.
Kubernetes symptoms can originate in workload sizing, application health, or the nodes hosting the cluster.
Investigated Redis degradation, memory-driven pod evictions, HPA/request mismatches, and NodeNotReady events caused by EC2 hardware issues. Documented findings for follow-up.
Useful incident response connects workload signals to infrastructure evidence and leaves a clear RCA for the next engineer.
Example command: kubectl get svc opencost. Example output: Service: opencost. Cluster metrics available. Ready to explore allocation. This is an illustration, not a live system.
Evaluating Kubernetes cost visibility to support better showback and chargeback conversations.
Cluster-level cost visibility helps teams understand resource ownership and discuss infrastructure spend.
Evaluated OpenCost with VictoriaMetrics and compared cluster-level insights against existing SaaS cost tooling.
The focus was evaluating cost visibility patterns and the information available to teams.
A Proxmox-based playground for learning by doing. I explore Kubernetes, self-hosted tools, automation, and local LLMs—then bring that practical understanding back to platform engineering.
Find me on GitHubExample command: cat learning.md. Example output: Proxmox: Virtualization & Self-hosting. Kubernetes: Containers & Orchestration. Observability: Metrics & Dashboards. Local LLMs: Exploring AI Infrastructure. This is an illustration, not a live system.
Cloud Native Computing Foundation
Verify credential
Amazon Web Services
Verify credential
Red Hat
Verify credentialBachelor’s in Computer Science and Mathematics · Osmania University, Hyderabad
Cloud platforms, Delivery workflows, or a Good infrastructure problem.
I’m happy to compare notes.